
Last Updated: November 12, 2026
Quick Summary
To reduce inference latency, measure real requests under realistic load and record p50, p95, and p99 instead of a single average. Then profile to find the true bottleneck and fix it in order: shrink the model with pruning and distillation, apply quantization, optimize GPU inference, and tune batching. Lock every speedup against a fixed accuracy floor.
- Split timing into queueing delay and compute time, and report queue time as its own metric.
- Profile on the hardware you will actually deploy, since latency depends on the hardware.
- Start quantization with post-training quantization, which needs no retraining.
- Set a maximum wait window for dynamic batching and measure the p99 impact.
- Set a p95 latency budget and an accuracy floor, then stop tuning.
Table of Contents
- Why Inference Latency Decides Whether Your Model Ships
- Model Inference Latency Measurement: Build a Benchmark You Can Trust
- Diagnose the Bottleneck Before You Optimize Anything
- Step 1: Shrink the Model With Pruning and Distillation
- Step 2: Apply Model Quantization for Inference Speed
- Step 3: GPU Inference Optimization at the Hardware Layer
- Step 4: Batching Strategies for Model Serving Under Load
- Step 5: Measure the Latency-Accuracy Trade-Off and Lock It In
- Frequently Asked Questions
Why Inference Latency Decides Whether Your Model Ships
Inference latency is the time a trained model takes to return a prediction for one request. It is the metric users feel. A model that scores well offline but answers slowly will lose to a simpler model that responds instantly.
That gap is the whole game. Reducing latency in deep learning model inference is less about clever math and more about knowing where the clock actually stops.
The pressure is real. Ultralytics notes that teams now cut computation through smaller model variants, lower input resolution, or fewer weights, precisely because latency blocks deployment (Ultralytics on inference latency).
Here is the tension most guides skip: latency and throughput pull against each other. NVIDIA describes partitioning workloads across multiple GPUs with tensor parallelism as a standard way to cut runtime latency (NVIDIA on low-latency inference communication). That adds coordination cost. You trade simplicity for speed.
Below, we walk through a reproducible benchmarking workflow, then five optimization steps in order. Each step targets a different part of the clock.
If you are still deciding where to run latency-sensitive inference, our breakdown of dedicated server vs cloud for AI workloads covers the trade-offs.
Model Inference Latency Measurement: Build a Benchmark You Can Trust
Model inference latency measurement is the practice of timing real requests under realistic load and recording the distribution, not a single number. Measure first. Optimize second.
A common mistake is timing one request on an idle machine. That tells you almost nothing. Production traffic arrives in bursts, queues form, and the tail stretches.
Freeze Inference, a 2019 paper by A. Kumar and coauthors, attacks prediction latency by adding intermediate-layer caches to deep networks (Accelerating Deep Learning Inference via Freezing(https://www.usenix.org/conference/hotcloud19/presentation/kumar)). The lesson for measurement is simple: cache hits and misses behave differently, so benchmark both.
Separate Queueing Delay From Compute Time
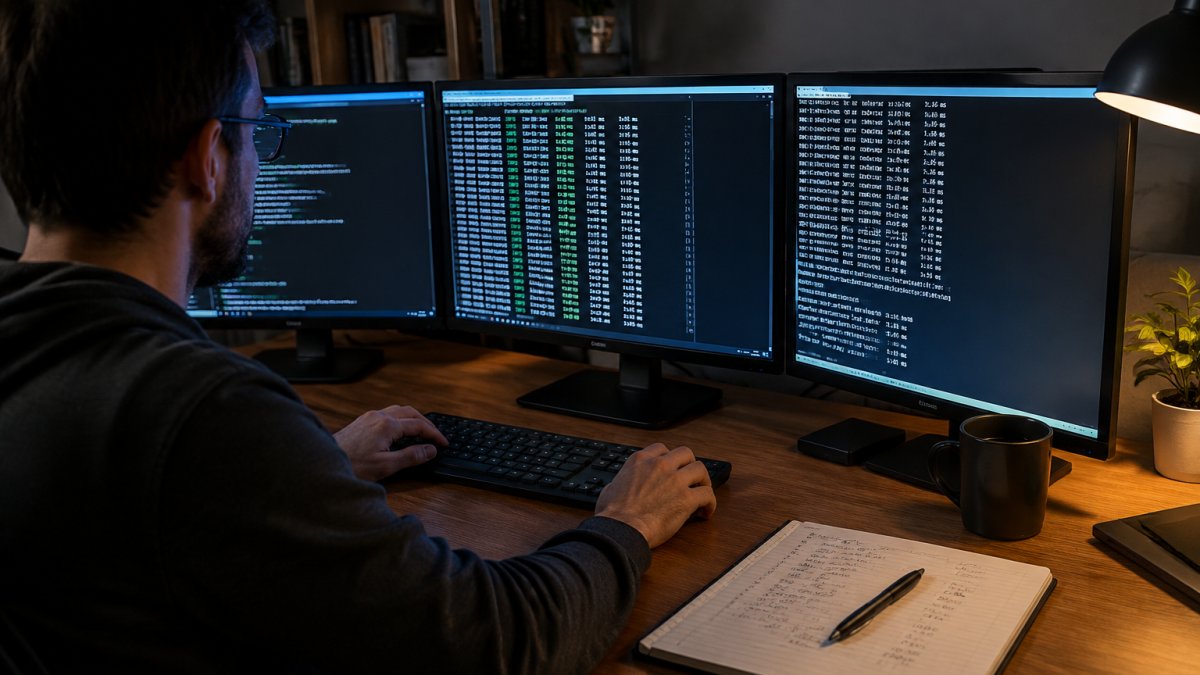
Split your timing into two buckets. Queueing delay is time spent waiting for a worker. Compute time is the model actually running.
- Log request arrival and worker pickup timestamps separately
- Report queue time as its own metric
- Watch queue time first when load rises
Track p95 and p99, Not Just the Average
Averages hide pain. If p99 latency spikes, one in a hundred users waits far too long.
- Record p50, p95, and p99 for every run
- Set a service-level objective on the tail, not the mean
- Rerun benchmarks after every model or runtime change
Diagnose the Bottleneck Before You Optimize Anything
Profiling comes before tuning. Most teams quantize a model, see no gain, and blame the model. The real bottleneck was the request queue or the data transfer.
Hardware-aware profiling answers one question: what is the machine waiting on?
- Compute bottleneck: GPU use sits near the ceiling while requests stack up
- Memory bandwidth: use is high but compute sits idle
- Data transfer: preprocessing and host-to-device copies dominate
- Queueing: workers are idle while requests wait
nn-Meter, a system from Tsinghua researchers, predicts deep neural network inference latency across diverse edge devices (EXTERNAL_LINK: nn-Meter latency prediction research | https://air.tsinghua.edu.cn/pdf/nn-Meter-Towards-Accurate-Latency-Prediction-of-Deep-Learning-Model-Inference-on-Diverse-Edge-Devices.pdf). The practical takeaway: latency depends on the hardware, so profile on the hardware you will actually deploy.
Here is the decision framework we use:
| Symptom | Likely Bottleneck | First Fix |
|---|---|---|
| GPU near full, queue growing | Compute | Pruning, distillation, quantization |
| GPU idle, latency high | Data transfer or preprocessing | Batch inputs, move preprocessing |
| Spiky p99 under load | Queueing | Dynamic batching, more workers |
| High memory use, slow steps | Memory bandwidth | Lower precision, smaller batches |
Step 1: Shrink the Model With Pruning and Distillation
Smaller models generally run faster.
Pruning removes weights or entire channels that contribute little to output quality. Knowledge distillation trains a small student model to mimic a larger teacher. Both cut the compute per request.
- Prune iteratively and re-benchmark after each pass
- Distill from your best large model into a deployable small one
- Check accuracy after every change, not at the end
The trap: aggressive pruning can quietly degrade accuracy. Measure both sides of the trade-off as you go.
Step 2: Apply Model Quantization for Inference Speed
Model quantization for inference stores weights and activations in lower precision, usually 8-bit or 4-bit integers instead of 32-bit floats. Less data to move means faster math and lower memory bandwidth pressure.
- Start with post-training quantization, which needs no retraining
- Compare 8-bit and 4-bit variants against your accuracy floor
- Re-profile after quantizing, since the bottleneck may shift
Watch out: quantized models can behave differently on outlier inputs. Test on real traffic samples, not just a clean validation set.
Step 3: GPU Inference Optimization at the Hardware Layer
GPU inference optimization means matching the model, the runtime, and the hardware so nothing waits on nothing. This is where most of the remaining latency lives.
- Use an inference engine that fuses operations and compiles the graph
- Keep inputs on the device to avoid repeated data transfer
- Pin memory and pre-allocate buffers
- Confirm the GPU is not shared with other tenants
That last point matters more than people admit. Shared resources can create noisy-neighbor latency that is hard to tune away. Our AI inference and LLM hosting runs on dedicated or customer-owned hardware so you control the serving stack. For deeper tuning, see our guide to optimizing GPUs for AI training, and if you are sizing hardware, the GPU dedicated server guide for deep learning covers the infrastructure options.
Step 4: Batching Strategies for Model Serving Under Load
Batching strategies for model serving group requests so the GPU processes more work per pass. The trick is doing it without inflating response time.
Dynamic batching waits a short window to collect requests, then runs them together. It raises throughput and can lower cost per request, but it adds queueing delay.
- Set a maximum wait window and measure the p99 impact
- Cap batch size to protect tail latency
- Scale workers horizontally when queues grow
Traffic distribution matters here too. Our load balancing overview covers configuration options for spreading requests across workers.
Step 5: Measure the Latency-Accuracy Trade-Off and Lock It In
Every optimization above moves two numbers: speed and accuracy. Lock both down before you ship.
- Build a fixed evaluation set and record accuracy at each optimization stage
- Pair every latency gain with its accuracy cost in one table
- Set a p95 latency budget and an accuracy floor, then stop tuning
- Add production monitoring to catch regressions after deploys
The trade-off is not free. Ultralytics and practitioner discussions both flag that latency work sits alongside accuracy concerns and the throughput-versus-latency balance (Ultralytics inference latency guide). Treat any speedup that costs accuracy as a decision, not a win.
Reducing latency in deep learning model inference comes down to measurement discipline. Profile first, fix the real bottleneck, and prove every gain against your accuracy floor. When the remaining bottleneck is shared hardware, that is an infrastructure problem. ServerPronto offers dedicated GPU environments with full root access, 2-hour provisioning, month-to-month billing with no contracts, and 24/7 on-site technicians. Visit ServerPronto’s website for current pricing or a quote.
Frequently Asked Questions
What does inference latency mean, and how is it different from throughput?
Inference latency is the time from when a request hits your server to when the prediction comes back. Throughput is how many requests you finish per second. They pull against each other: larger batches raise throughput but push up the time each individual request waits. For real-time applications like fraud scoring or chat responses, latency is the number users feel. For overnight batch scoring, throughput matters more. Measure both, but set your service-level objective on latency percentiles, since a fast average hides the slow requests that generate complaints.
How do batch size and request batching affect inference latency?
Batching strategies for model serving trade queueing delay for compute efficiency. A batch of 32 keeps a GPU busy and raises throughput, but each request waits for the batch to fill, which adds queueing delay. Small batches or batch size 1 keep response time low at the cost of hardware utilization. Dynamic batching, where the server waits a short window (often a few milliseconds) and ships whatever arrived, is the usual compromise. Benchmark your real arrival rate before picking a window, because a fixed timeout that is too long hurts tail latency more than it helps throughput.
When should you use quantization to speed up model inference?
Model quantization for inference is worth trying when your model is memory-bandwidth bound, when you are serving on GPUs with limited VRAM, or when you need to fit more concurrent requests per device. Converting weights from 32-bit to 16-bit floating point usually costs little accuracy and roughly halves memory traffic. Going to 8-bit integers can cut memory further, but validate task accuracy on a held-out set first. If accuracy drops past your threshold, try quantization-aware training or keep the sensitive layers in higher precision.
How do you identify whether model inference is limited by the GPU, CPU, or data pipeline?
Profile each stage separately. Log timestamps for request arrival, preprocessing completion, model execution, and postprocessing. If preprocessing or image decode dominates, the GPU is idle waiting on the CPU, and input resolution or frame sampling is your lever. If model execution dominates and GPU utilization sits near the ceiling, you are compute bound and should look at pruning, quantization, or a faster inference engine. Low GPU utilization with high memory traffic points to memory bandwidth. Fix the largest stage first, then re-measure, since removing one bottleneck often exposes the next.


Comments are closed.