
Table of Contents
- Understanding Dedicated Server Scaling Fundamentals
- Vertical vs Horizontal Scaling: When to Use Each
- Dedicated Server Capacity Planning and Resource Monitoring
- Horizontal Scaling with Load Balancing
- Implementing Autoscaling and Scaling Triggers
- Dedicated Server Migration Checklist
- Avoiding Common Scaling Mistakes
- Frequently Asked Questions
Last Updated: October 10, 2026
Understanding Dedicated Server Scaling Fundamentals
To scale dedicated server infrastructure means increasing its capacity to handle growing workloads, traffic, and data demands. The challenge is deciding whether to expand your existing server’s resources (vertical scaling) or add more servers to distribute the load (horizontal scaling). The right approach depends on your application architecture, budget, and performance requirements.
Vertical vs Horizontal Scaling: When to Use Each
Vertical scaling (scaling up) means adding more CPU, memory, or storage to a single server. Horizontal scaling (scaling out) involves adding more servers and distributing workloads across them using load balancing.
When Vertical Scaling Makes Sense
Vertical scaling works best for workloads tightly coupled to a single server: database servers, in-memory caches, and single-instance applications with high memory requirements.
Use vertical scaling when:
- Your application is stateful and tightly bound to a single server (e.g., a relational database, session store, or monolithic application)
- Your workload is memory-intensive but not CPU-bound (adding more RAM solves the bottleneck)
- You need low latency and cannot tolerate network overhead between distributed nodes
- Your application lacks horizontal-scaling support in its architecture
- You’re in the early growth phase and haven’t yet hit single-server limits
Advantages of vertical scaling:
- Operational simplicity: no load balancing needed
- No code changes required
- Lower latency
Dedicated-server vertical scaling constraints:
Unlike cloud instances, upgrading a dedicated server involves hardware lead times and downtime. Processor upgrades may require 24-48 hours; memory upgrades typically take 1-4 hours. Plan scaling events during maintenance windows and budget for provisioning delays.
When Horizontal Scaling Becomes Necessary
Horizontal scaling becomes necessary when you need to handle massive traffic volumes, require high availability, or have exhausted vertical scaling options. By distributing workloads across multiple servers, you gain redundancy, fault tolerance, and the ability to scale beyond single-server limitations.
Use horizontal scaling when:
- Your application is stateless or can be refactored to be stateless (each request is independent)
- You need fault tolerance and high availability (if one server fails, others continue serving traffic)
- Your traffic exceeds what a single server can handle, even after vertical scaling
- You’re running microservices or loosely coupled components that can run on separate machines
- You need to scale incrementally and cost-effectively by adding commodity hardware
- Your workload is read-heavy and benefits from database replication across multiple nodes
Advantages of horizontal scaling:
- Redundancy and fault tolerance
- Unlimited growth potential
- Cost efficiency at scale
Dedicated-server horizontal scaling trade-offs:
Provisioning takes 2-24 hours and requires load balancing, session management, database replication, and multi-node monitoring. Operational complexity is higher, but you gain cost predictability with fixed monthly rates.
Decision Framework: A Practical Comparison
| Factor | Vertical Scaling | Horizontal Scaling |
|---|---|---|
| Setup time | 1-48 hours (hardware upgrade + downtime) | 2-24 hours per server (provisioning + configuration) |
| Code changes | None required | May require stateless refactoring |
| Operational complexity | Low | High (load balancing, replication, monitoring) |
| Single point of failure | Yes | No (redundancy built in) |
| Cost per unit capacity | High (premium hardware) | Lower (commodity servers) |
| Scaling limit | Hardware ceiling (~2-4 TB RAM, 128+ cores max) | Unlimited (add more servers) |
| Latency | Lower (no network overhead) | Slightly higher (inter-node communication) |
| Best for | Databases, stateful apps, early growth | High-traffic sites, microservices, HA requirements |
The Real Difference: Application Architecture
Stateless applications (where each request is independent) scale horizontally with ease, examples include web servers, API gateways, and microservices. Stateful applications (databases, session stores, caches) require vertical scaling or architectural refactoring to support horizontal scaling.
Most teams start with vertical scaling because it’s simpler. As you grow, you’ll hit the hardware ceiling and must choose: refactor to horizontal scaling or optimize within vertical limits.
Most teams underestimate the cost of horizontal scaling implementation. It’s not just adding servers, you need load balancing, session management, database replication, and monitoring across multiple nodes. Budget for the operational complexity and provisioning lead times, not just hardware costs. For dedicated servers, factor in 2-24 hour provisioning delays for each new machine.
Dedicated Server Capacity Planning and Resource Monitoring
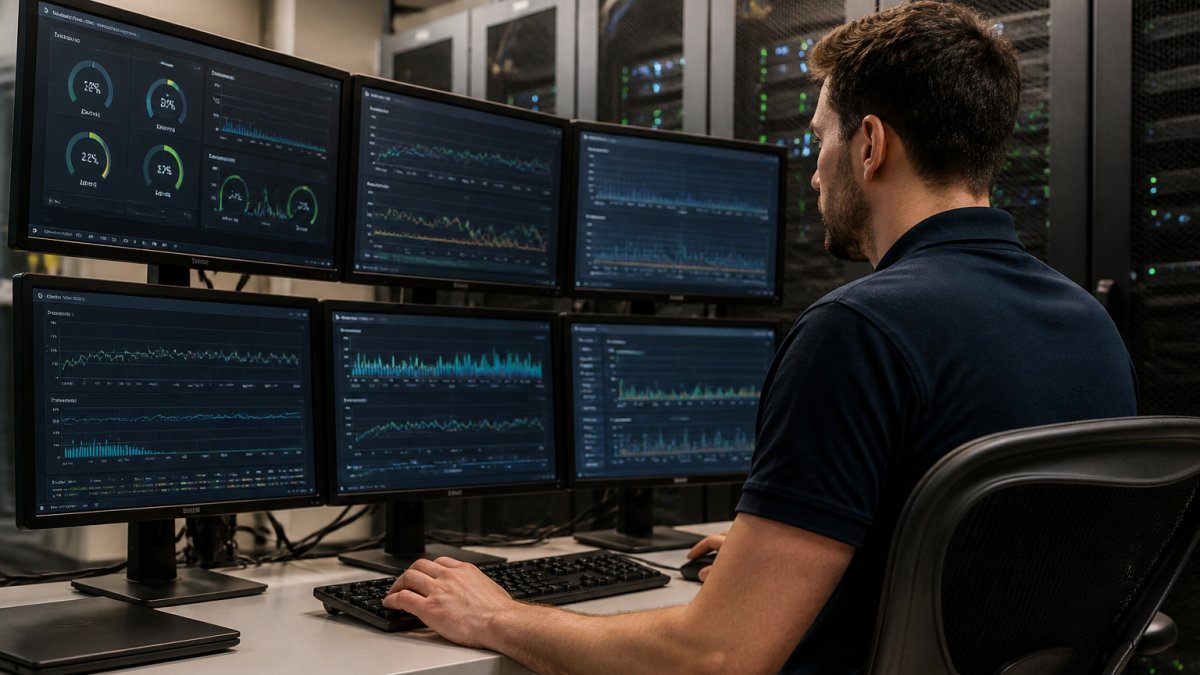
Effective capacity planning prevents performance degradation. Measure your current resource consumption: CPU usage, memory, storage, and network bandwidth to determine when you’ll need to scale.
Key Metrics to Monitor
Sustained CPU usage above 70-80% signals scaling is needed (Chapter 1. Configuring auto scaling for Compute instances | Auto Scaling for Instances |…). Memory approaching capacity causes slowdowns; storage above 80% causes failures. Slow response times despite low CPU indicate bottlenecks elsewhere: database queries, disk I/O, or network delays.
Setting Capacity Thresholds
Use the 70% rule: when any resource reaches 70% use, begin planning a scale event. Set up automated monitoring and alerting to respond proactively before resource exhaustion.
Waiting until resources hit 95%+ use before scaling is a common mistake. At that point, performance is already degraded, and scaling takes longer because the system is under stress. Plan scaling events when you still have headroom.
Horizontal Scaling with Load Balancing
A load balancer distributes traffic across multiple servers using strategies like round-robin, least connections, or IP hash. Stateless services scale horizontally without modification; stateful applications require session replication or external session storage. Database scaling is critical, read replicas distribute query load while write operations go to the primary server.
Implementing Autoscaling and Scaling Triggers
True autoscaling isn’t possible when you scale dedicated server hardware because provisioning takes 2-24 hours, not seconds. Instead, dedicated-server scaling requires planned scaling based on capacity forecasting and semi-automated scaling with manual provisioning steps.
Understanding Dedicated-Server Scaling Constraints
Cloud instances spin up in seconds; dedicated servers are physical machines that must be ordered, racked, networked, and configured before they’re ready. This fundamental difference changes how you approach scaling triggers and capacity planning.
Key constraints:
- Provisioning lead time: 2-24 hours
- No instant scaling: You must anticipate demand
- Fixed monthly costs: Over-provisioning is expensive
- Decommissioning delays: Requires data migration
Planned Scaling: Forecasting and Capacity Buffers
Because dedicated servers can’t scale instantly, you must forecast demand and provision capacity in advance.
Step 1: Analyze historical growth, Review metrics over 6-12 months to identify growth rate and seasonal spikes.
Step 2: Project future capacity needs, If growing 20% per month at 70% CPU, you’ll need additional capacity in 3-4 months.
Step 3: Establish capacity buffers, Set target thresholds (60-70% CPU, 75-80% memory) and trigger provisioning when you approach them, accounting for provisioning lead time and traffic spikes.
Scaling Triggers for Dedicated Infrastructure
Use predictive and threshold-based triggers to decide when to provision new servers.
Metric-based triggers: CPU sustained above 70% for 1+ week, memory above 80% for 3+ days, storage above 80%, network bandwidth approaching limit, database query latency increasing, request queue depth growing.
Time-based triggers: Seasonal events, product launches, and quarterly reviews.
Predictive triggers: Use historical data to anticipate demand, if traffic doubles every 6 months, schedule provisioning accordingly.
Semi-Automated Scaling Workflow
You can automate parts of the scaling workflow:
Monitoring and alerting: Alert when thresholds are approached, not exceeded.
Provisioning automation: Work with your hosting provider to automate server provisioning via API with your standard stack, networking, security, and health checks.
Load balancer configuration: Automate adding new servers to your load balancer’s backend pool via API with health checks.
Staged rollout: Gradually increase traffic to new servers (10% ? 25% ? 50% ? 100%) while monitoring performance.
Capacity Planning with Concrete Metrics
Make scaling decisions based on measurable signals.
Sustained utilization: Look at average utilization over 1-2 weeks, not instantaneous spikes.
Request latency: If latency increases despite low CPU, you have a bottleneck elsewhere (database, disk I/O, network).
Queue depth: Growing request queues signal saturation.
Error rates: Increasing 5xx errors or timeouts indicate the server is overwhelmed.
Database metrics: Monitor query execution time, connection pool saturation, and replication lag.
Avoiding Over-Provisioning
Because dedicated servers have fixed monthly costs, over-provisioning is expensive. A server running at 20% utilization costs the same as one at 80%.
Right-size based on actual demand. If you’re growing 10% per month, don’t provision for 50% growth. Add capacity incrementally. It’s cheaper to provision a second server in 3 months than to pay for unused capacity today.
Use smaller servers for horizontal scaling. Instead of one massive server, use multiple mid-range servers. This gives you flexibility: if demand drops, you can decommission one server without losing all capacity.
Monitor utilization post-scaling. After you add a new server, verify that utilization drops to your target range (e.g., 50-60% per server). If it doesn’t, you have a bottleneck elsewhere or your forecast was wrong.
The biggest mistake with dedicated-server scaling is waiting too long to provision. Because lead times are 2-24 hours, you must forecast and order ahead. Waiting until you’re at 95% utilization means you’ll be over-capacity for 1-2 days while the new server provisions. Plan scaling events when you still have 20-30% headroom.
Dedicated Server Migration Checklist
Migrating to a scaled infrastructure requires careful planning to avoid downtime and data loss.
Pre-Migration Planning
Document your current infrastructure completely: server specifications, installed software, configuration files, database schemas, and application versions. Create a detailed runbook of every step needed to replicate your environment on new servers.
Backup everything. Multiple backup copies on different storage systems protect against corruption or failure. Test backup restoration before migration to ensure backups are valid.
Plan your DNS strategy. When you migrate to new servers, DNS changes determine traffic routing. Use short TTLs (time-to-live) before migration so DNS updates propagate quickly. This minimizes the window where old and new infrastructure coexist.
Migration Execution
Perform migration during a maintenance window when traffic is lowest. Start by provisioning new infrastructure and verifying it matches your requirements. Copy data and configurations from the old server to new servers.
Run parallel systems: keep the old infrastructure running while the new one handles a portion of traffic. Monitor both systems closely for discrepancies. Once you’re confident the new infrastructure is stable, switch all traffic to it.
Post-Migration Validation
Verify that all services are running correctly on the new infrastructure. Check application logs for errors. Monitor performance metrics to ensure they match or exceed pre-migration baselines. Test critical user workflows end-to-end.
Keep the old infrastructure available for 24-48 hours after migration. If issues arise, you can quickly roll back. Once you’re confident everything works, decommission the old servers.
The most common migration mistake is insufficient testing. Always run a full test migration in a staging environment first. Never migrate production data directly without validation.
Avoiding Common Scaling Mistakes
Identify your bottleneck before scaling, adding web servers won’t help if your database is slow. Right-size based on actual demand, not worst-case scenarios. Monolithic applications require refactoring into microservices for horizontal scaling. Monitor continuously to verify scaling solved your problem.
Scaling requires balancing performance, cost, and complexity. Start with capacity planning and monitoring. Vertical scaling handles initial growth; horizontal scaling becomes necessary as traffic exceeds single-server limits.
ServerPronto provides the infrastructure foundation you need to scale confidently. With 24/7 on-site technicians and a 100% uptime guarantee, you get the reliability your growing business demands. Build and price your dedicated server infrastructure with ServerPronto and scale without worrying about shared resources or unexpected bills.
Frequently Asked Questions
How do you know when a dedicated server needs to be scaled?
Monitor CPU usage, memory consumption, storage capacity, and network bandwidth. When any metric consistently reaches 70-80% of available resources, scaling becomes necessary. Real-time monitoring tools track these thresholds and alert you before performance degrades. Check application response times and user reports as well, slowdowns often signal capacity constraints before metrics spike.
Should you scale up a dedicated server or add another server?
Vertical scaling (upgrading CPU, RAM, or storage) works best for single-threaded applications or database workloads that benefit from more raw power. Horizontal scaling (adding more servers) suits distributed applications and handles traffic spikes more cost-effectively. Most modern architectures combine both: scale up for database servers, scale out for web application layers. Your application architecture determines the best approach.
What is the dedicated server migration checklist?
Before migration: audit all services, document configurations, back up databases, and test in a staging environment. During migration: coordinate downtime windows, transfer data in phases, update DNS records carefully, and monitor for errors. After migration: verify all services function correctly, run performance tests, monitor resource usage, and keep backups of the old server for 30 days. Plan for minimal downtime by using load balancers during cutover.
How does horizontal scaling with load balancing work?
Distribute incoming traffic across multiple servers using a load balancer that directs requests based on server health and availability. Ensure applications are stateless so requests can route to any server without losing session data. Use session storage (Redis, memcached) or sticky sessions if state is needed. This approach increases capacity, improves fault tolerance, and allows you to add or remove servers without downtime.

Comments are closed.