
Table of Contents
- Dedicated Server Migration Checklist for Agencies: What You’ll Need Before You Start
- Build a Server Migration Plan Template Your Team Can Reuse
- Step 1: Provision and Harden the New Dedicated Server
- Step 2: Replicate Data, Apps, and Email Without Breaking Anything
- Step 3: Run a DNS Cutover Checklist With a Tested Rollback Path
- Step 4: Control Website Migration Downtime With a Maintenance Window
- Step 5: Run Post-Migration Website Checks Before You Tell the Client
- Common Mistakes Agencies Make During a Dedicated Server Migration
- Frequently Asked Questions
Last Updated: October 8, 2026
Dedicated Server Migration Checklist for Agencies: What You’ll Need Before You Start
A dedicated server migration checklist for agencies exists because client work cannot pause while infrastructure moves.
Most migration failures trace back to missing preparation, not bad hardware. An agency moving 15 client sites needs a written plan, named owners, and a rollback budget before touching anything.
Below, we break the process into five steps, from inventory through post-migration checks, plus the mistakes that cause the most damage.
Inventory and access audit
Start by listing everything that must move. Skip this and you will discover a forgotten client database mid-cutover.
Build a spreadsheet covering:
- Every domain, subdomain, and DNS zone you manage
- Applications, databases, and their versions
- Mailboxes, forwarders, and MX records
- SSL certificates and renewal dates
- Cron jobs, scheduled tasks, and third-party integrations
- Credentials: registrar logins, DNS panel access, API keys
Note which services are mission-critical hosting versus nice-to-have. That ranking drives your maintenance window later.
Roles and rollback budget
Name a migration lead, a DNS owner, and a client communications owner. One person cannot hold all three roles during a live cutover.
Set a rollback budget too: a written time limit for how long you will troubleshoot before reverting. Many agencies find that a fixed cutoff keeps a two-hour window from becoming an eight-hour outage.
Assign a “scribe” who logs every command and timestamp during cutover. When something breaks, the log tells you exactly which change caused it, instead of forcing a rebuild from memory.
Build a Server Migration Plan Template Your Team Can Reuse
A server migration plan template is a fixed document that captures scope, owners, timing, and rollback rules for every move, so no agency engineer starts from a blank page. Standardizing it cuts prep time on repeat migrations.
The seven fields every migration plan needs
| Field | What to Record | Why It Matters |
|---|---|---|
| Scope | Domains, apps, databases, mail | Prevents forgotten assets |
| Owners | Lead, DNS, comms, scribe | Clear accountability |
| Timeline | Prep, cutover, verification dates | Sets client expectations |
| Maintenance window | Start and end time | Controls website migration downtime |
| Rollback trigger | Time limit and failure conditions | Stops open-ended outages |
| Verification list | Checks per site and service | Catches silent breakage |
| Communication plan | Who tells clients what, when | Protects the relationship |
Fill every field before provisioning. A template with blanks is a plan with holes.
Step 1: Provision and Harden the New Dedicated Server
Provisioning should happen days before cutover, never the same morning. ServerPronto provisions dedicated servers in about two hours, which gives your team room to configure and test without clock pressure.
Work through this sequence:
- Confirm the OS image, kernel version, and control panel match the old environment
- Apply updates and configure the firewall before any data lands
- Set up SSH keys, disable password login, and create service accounts
- Install monitoring and log shipping
- Verify root access works for every tool your team needs
Full root access matters here. If you rely on custom database modules or specific software builds, confirm you can install them without a support ticket.
Skipping the hardening pass because “the old server was never attacked” is the mistake that bites hardest. An unpatched, internet-facing server can be compromised within hours of going live.
Step 2: Replicate Data, Apps, and Email Without Breaking Anything
Replication is where quiet errors hide. A database that copies cleanly can still fail on permissions, character sets, or scheduled jobs.
Move in this order:
- Databases first, using a dump and restore, then verify row counts and a sample of records
- Application files and configuration, checking file ownership and paths
- Email accounts and mailboxes, testing send and receive before cutover
- Cron jobs and integrations, retargeting any hardcoded IP addresses
Run the application on the new server using a hosts-file override. This lets you test the full stack before DNS changes anything for real visitors.
For agencies running database-driven campaigns or AI workloads, confirm the new hardware handles peak load. A staging test at half traffic tells you little.
Step 3: Run a DNS Cutover Checklist With a Tested Rollback Path
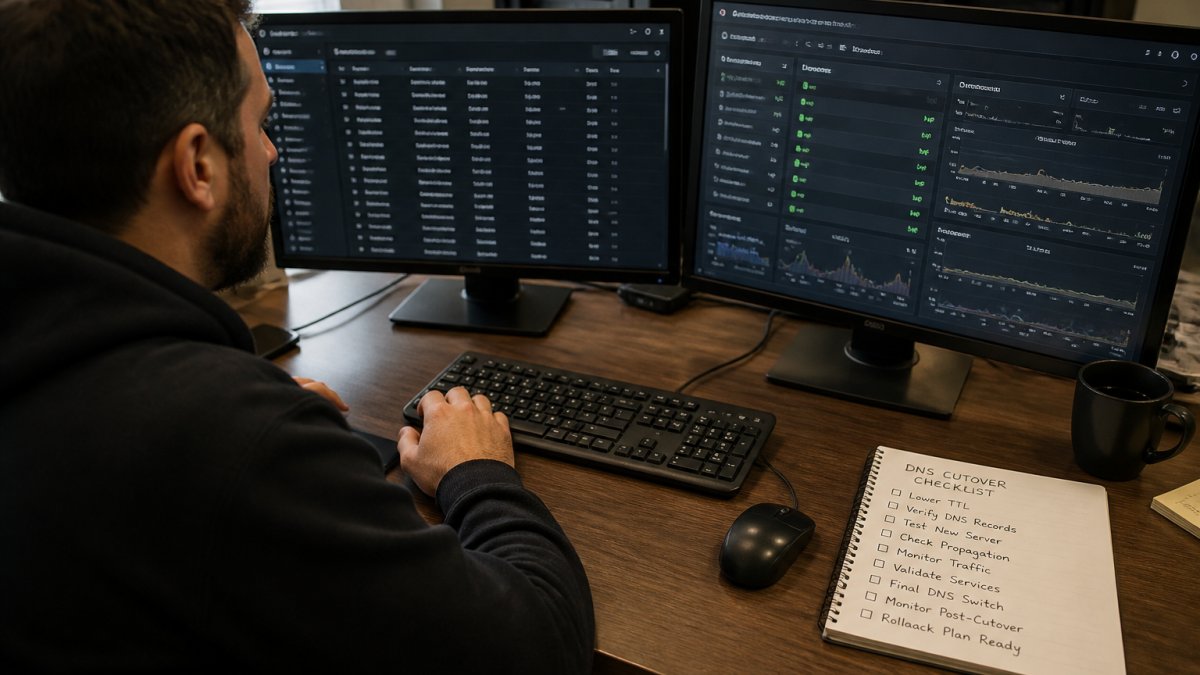
A DNS cutover checklist is the ordered list of DNS changes, verifications, and rollback actions that governs the moment traffic moves. Treat it as a script, not a guideline.
Translate your TTL into a real downtime allowance
TTL is the number that decides how long stale records can keep pointing visitors at the old server. A 3,600-second TTL means resolvers may cache the old address for up to an hour after you publish the change. A 300-second TTL caps that exposure at five minutes.
A common pattern is to drop TTLs to 300 seconds two days out, confirm propagation with a public DNS lookup tool from several regions, then raise them back to a normal value a week after cutover.
Match the cutover to your SLA scope
An uptime percentage alone does not tell you what is covered. Before you schedule the window, read the dedicated-server agreement and separate four things:
- Network availability, whether the guarantee covers the provider’s transit and routing, or only the server’s power and hardware.
- Power and hardware, whether a failed disk or PSU counts as downtime, and how fast replacement is promised.
- Maintenance windows, whether scheduled work is excluded from the calculation, and how much notice the provider must give.
- Measurement boundaries, whether the clock runs from the provider’s monitoring point or from your users’ location.
Most practitioners find the exclusions matter more than the headline number. A guarantee that excludes scheduled maintenance and measures only the provider’s internal network is a different promise than one that covers the full service path.
Before cutover
- Lower TTL values on all records at least 24 hours ahead
- Record current DNS values in writing, including the registrar and zone file
- Confirm the rollback path works by reverting one low-traffic domain first
- Notify clients of the maintenance window and the expected duration
- Confirm the old server stays powered, reachable, and licensed through the window
During cutover
Change records in small batches, verify each one, and keep the old server running and reachable. Verify from more than one network, a resolver in one region can serve a stale answer while another has already updated. If verification fails past your rollback trigger, revert immediately rather than troubleshooting live.
The old server stays live until every site passes verification. Decommissioning early removes your only safety net.
Step 4: Control Website Migration Downtime With a Maintenance Window
Website migration downtime shrinks when you schedule the window around real traffic patterns, not convenience. Check analytics for the quietest hours in your clients’ time zones.
Practical ways to limit downtime:
- Run the cutover during the lowest-traffic window you can find
- Keep the old server serving until DNS propagates fully
- Use a maintenance page for sites that cannot tolerate partial states
- Stagger client sites across separate windows if you host many
For mission-critical hosting, a short planned window beats an unplanned outage every time. Clients forgive a scheduled hour; they remember a surprise Friday afternoon failure.
Step 5: Run Post-Migration Website Checks Before You Tell the Client
Post-migration website checks confirm that everything works before you declare success. Telling a client “we’re done” and then finding a broken contact form damages trust fast.
Run the functional checklist on every site
- Homepage and key pages load over HTTPS
- Contact forms submit and deliver to the right inbox
- E-commerce checkout completes a test order and sends the receipt
- Database connections and search functions respond
- Email sends and receives, including forwarders and aliases
- SSL certificates are valid and auto-renewing
- Cron jobs and scheduled tasks fire on the new server
- Monitoring and backups are active and reporting
Run these checks on every site, not a sample. Document results in the migration plan so the scribe’s log and the verification list match.
Verify uptime independently, not just from the provider’s dashboard
A provider’s status page is a starting point, not proof. Set up external monitoring that checks each site from at least two or three locations outside the provider’s network. That gives you a record you own if availability is ever disputed.
A practical setup:
- Ping or HTTP check every 60 seconds from multiple regions
- Alert to a shared inbox the whole team can see
- Log timestamps, response codes, and durations
- Export the log weekly so it survives account changes
When you compare your external measurements against the provider’s SLA records, expect small differences. The provider may measure from inside its network, exclude maintenance windows, or use a different measurement period. Document the discrepancy rather than assuming one side is wrong.
Know how to claim an uptime credit
If an outage exceeds the guarantee, agreements often require you to file a claim within a set window and to include specific evidence, such as the ticket number, the affected service, the start and end times, and monitoring data.
Keep a simple claim file for each client:
- Outage start and end in the provider’s time zone
- Affected service and scope (network, power, hardware, or full service)
- Your external monitoring export
- The provider’s own incident reference, if one was issued
Service credits are often capped and are typically the only remedy the agreement offers. Read the cap before you promise a client anything.
Distinguish the failure types before you escalate
Not every outage is the provider’s responsibility. Hardware, network, and power failures usually fall under the agreement. Software, application, and configuration failures usually fall on your team. Knowing which is which tells you whether to open a provider ticket or start your own rollback.
Do not close the migration until the external monitoring has run clean for at least one full business day. A site that passes a five-minute check can still fail under real traffic.
Common Mistakes Agencies Make During a Dedicated Server Migration
The most damaging mistakes are process failures, not technical ones. Here are the patterns we see most.
- Starting cutover without a written rollback trigger
- Forgetting a client’s mail or a secondary domain during inventory
- Leaving DNS TTLs high, which stretches propagation and downtime
- Decommissioning the old server before verification finishes
- Skipping the hardening pass on the new machine
- Failing to retarget hardcoded IP addresses in apps and integrations
Each of these turns a routine move into an emergency. A reusable server migration plan template catches most of them before they happen.
Frequently Asked Questions
How long does a dedicated server migration take for an agency?
Plan for two to six weeks per server, not a single weekend. Provisioning and hardening usually take a few days, data replication runs for several days on large sites, and the DNS cutover itself takes 24 to 48 hours to propagate. Agencies managing multiple client sites should stagger migrations so one failure does not take down every account at once.
How do you minimize website migration downtime during the cutover?
Lower the DNS TTL to 300 seconds at least 48 hours before the cutover, put the site into maintenance mode, run a final database sync, then switch the A record. Keep the old server online and serving until the new one has passed every post-migration check. Most agencies see only a few minutes of downtime when they follow this sequence.
What should an agency check before migrating client websites?
Audit every dependency first: DNS records, MX and SPF entries, SSL certificates, cron jobs, third-party API keys, and any hardcoded IP addresses in the code. Confirm the new server can handle peak traffic and that the client knows the maintenance window. Skipping this step is the most common cause of post-migration email and checkout failures.
How do you roll back a server migration if something goes wrong?
Keep the old server running and untouched for at least seven days after cutover. If the new server fails, restore the original DNS records, which is why you keep TTL low, and confirm propagation. Document the rollback trigger in your migration plan, such as a checkout error rate above 1 percent, so the decision does not require a meeting at 2 a.m.
Migrating client infrastructure without a tested plan is how agencies lose accounts. ServerPronto supports agencies with dedicated servers provisioned in about two hours, full root access, month-to-month billing with no contracts, and 24/7 on-site technicians backing a 100% uptime guarantee. Build your migration around infrastructure you can trust. Get started with ServerPronto and move your clients with confidence.

Comments are closed.